Nvfp4

What's New in Inference Engineering — Philip Kiely, Baseten

What's New in Inference Engineering — Philip Kiely, Baseten

Philip Kiely provides an update on recent advancements in inference engineering, covering new techniques in quantization (TurboQuant's specific application), KV cache compaction (introducing 'Still' for learned, compressed memory), and speculative decoding (from Eagle 3 to Dlash and DSpark, including continuous retraining). He emphasizes the blurring lines between training and inference and differentiates between local and data center optimization strategies.
Taking Reinforcement Learning Cross Datacenter — Nan Jiang, Modal

Taking Reinforcement Learning Cross Datacenter — Nan Jiang, Modal

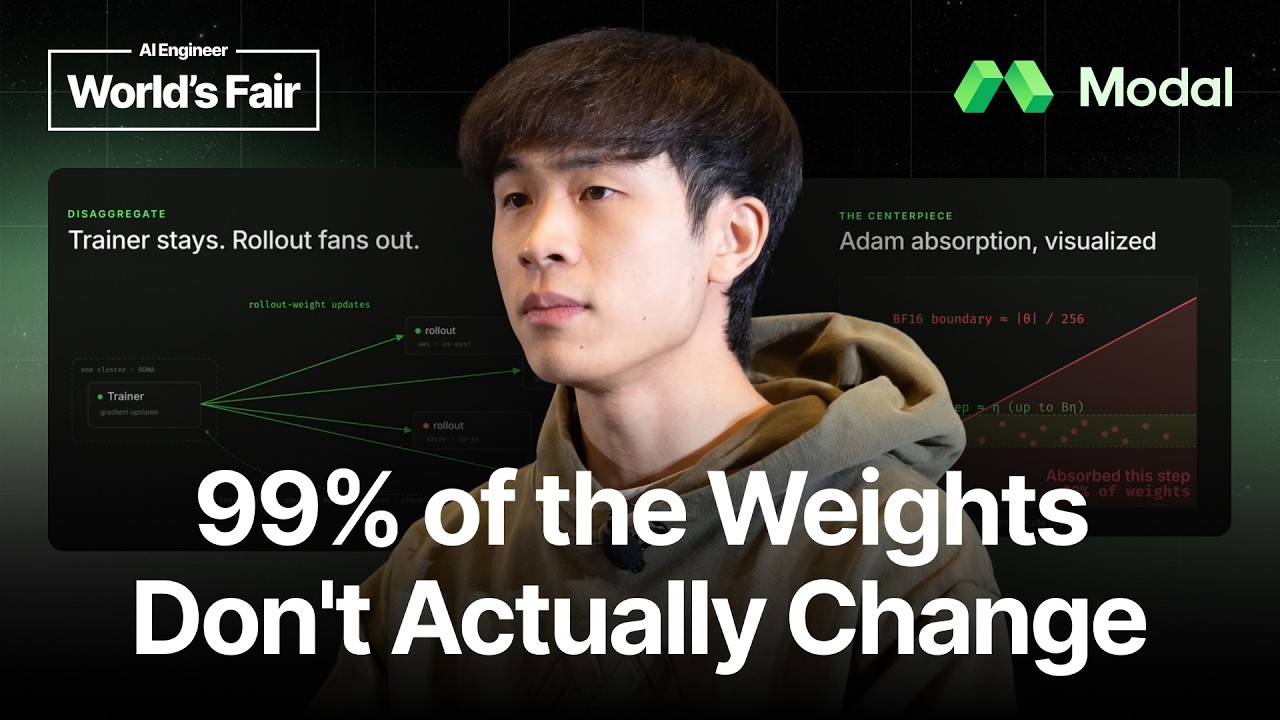
Nan Jiang introduces "Adam absorption" to revolutionize RL model synchronization. By exploiting finite precision serving and small Adam steps, less than 1% of served model weights actually change, allowing for 500MB patches instead of 500GB checkpoints. This enables a distributed "bulletin board" architecture, decoupling trainers from global rollout fleets and unlocking elastic, cross-region GPU capacity for RL.

Compression at the Edge — Chris Alexiuk, NVIDIA

Compression at the Edge — Chris Alexiuk, NVIDIA

This panel discussion explores the critical role of model compression, particularly quantization, in democratizing AI. It delves into how massive models like GLM 5.2 can be shrunk by over 80% without equivalent performance loss, thanks to techniques like mixed-precision quantization and understanding uneven layer importance. The discussion covers NVIDIA's NVFP4 format, challenges posed by new model architectures, the preference for KL divergence over accuracy benchmarks, and the vision of future AI running efficiently on all local devices.