Low latency

Judge a Transaction by the Company It Keeps — Somya Rai & MD Sharique, EXL

Judge a Transaction by the Company It Keeps — Somya Rai & MD Sharique, EXL

EXL developed an advanced fraud detection system that augments XGBoost with Graph Neural Network (GNN) embeddings. Traditional tabular models struggle to capture fraud signals residing in transaction neighborhoods. The system's innovative design includes meticulous sampling strategies, disjoint monthly graph construction for leakage control, and a GraphSAGE architecture that aggregates mean, max, and standard deviation of neighbor features to detect subtle fraud patterns. Emphasizing explainability for regulatory compliance and analyst trust, it also features a highly optimized serving architecture achieving 3ms P99 latency, pivoting to edge prediction to reduce cache footprint from 60GB to 2-3GB. This led to a 27-33% relative lift in true positive rates and a projected $65 million incremental fraud capture.
Realtime Voice Agents with Frontier Intelligence — Bohan Li, EliseAI

Realtime Voice Agents with Frontier Intelligence — Bohan Li, EliseAI

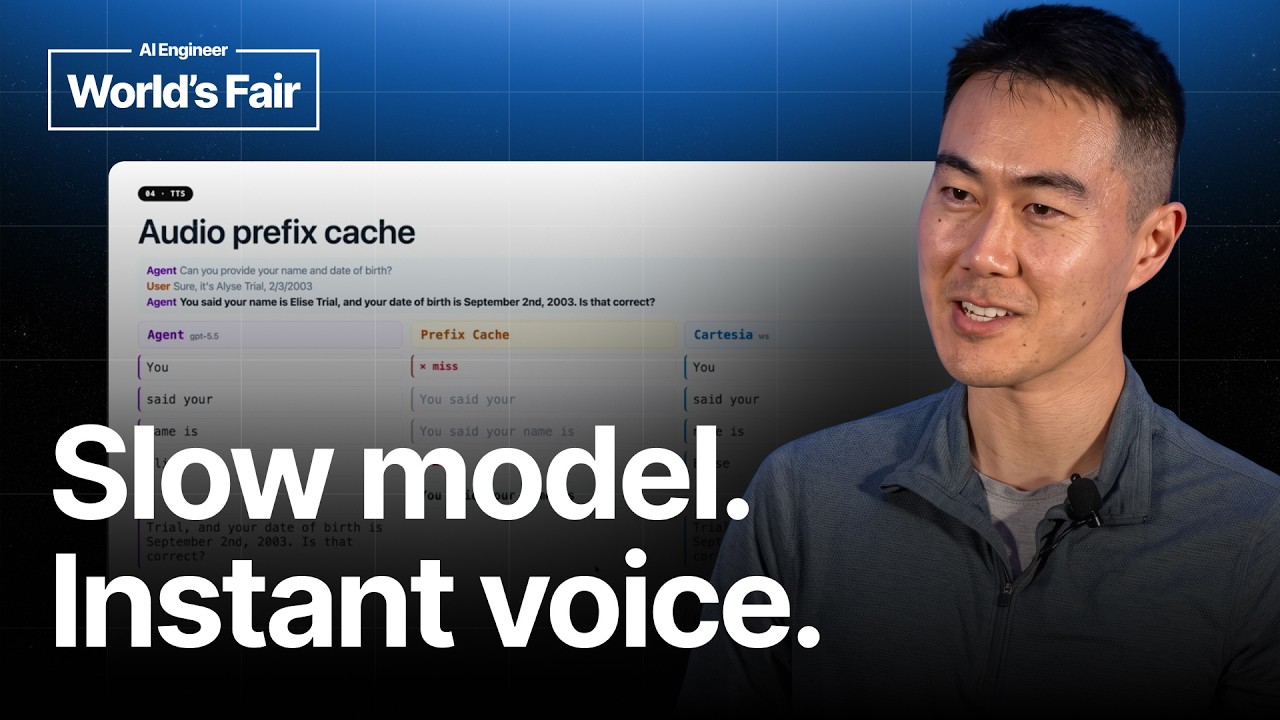
Bohan Li of EliseAI unveils a sophisticated architecture for real-time voice agents that merges high intelligence with low latency, akin to a self-driving car's perception, planning, and control systems. Key innovations include a speculative transcriber combining fast streaming with accurate contextual correction, background agents for offloading LLM tool calls and enabling eager generation, and a clever prefix cache for speech synthesis that seamlessly blends pre-cached audio with dynamically generated speech to mask underlying processing delays.

Voice In, Visuals Out: The Agony and the Ecstasy - Allen Pike, Forestwalk Labs

Voice In, Visuals Out: The Agony and the Ecstasy - Allen Pike, Forestwalk Labs

Allen Pike (Forestwalk Labs) discusses the power of "voice-in, visuals-out" AI experiences, a paradigm championed by Andrej Karpathy. He highlights the critical challenge of latency in real-time AI interactions and shares three key techniques for achieving low-latency, delightful user experiences: utilizing fast models, employing short inference intervals, and implementing stable caching regimens.

Build Hour: GPT-Realtime-2

Build Hour: GPT-Realtime-2

Explore GPT-Realtime-2, OpenAI's advanced voice AI model, through practical demos and a deep dive with Sierra on building production-grade, low-latency voice agents with complex reasoning and tool use.