Llm evaluation

The Model Swap Workshop: GPT-5.5 vs Kimi vs DeepSeek vs Mistral

The Model Swap Workshop: GPT-5.5 vs Kimi vs DeepSeek vs Mistral

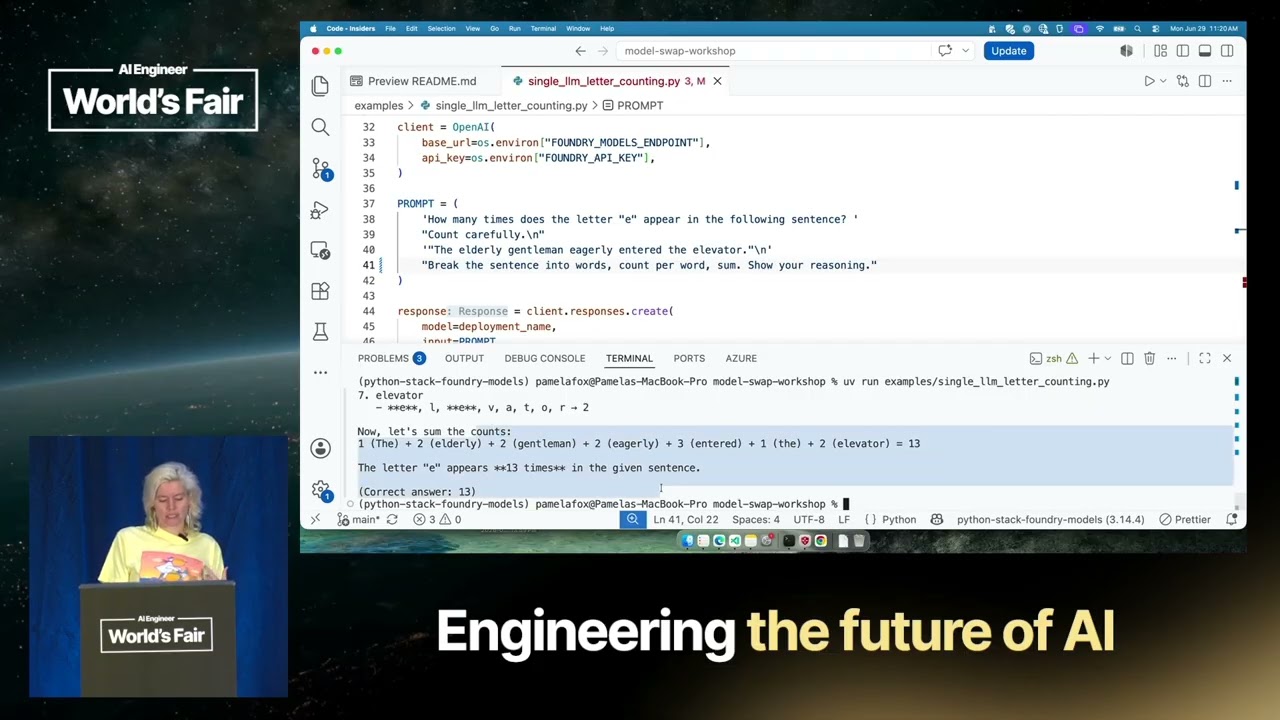
Pamela Fox runs a guided workshop comparing GPT-5.5, Kimi K2.6, DeepSeek V4 Flash, and Mistral Large 3 on Microsoft Foundry, showing that benchmarks cannot predict how a model will behave in a specific application. The talk covers counting, RAG groundedness, vision, multilingual failures, tool calling, parallel tool calls in agents, string-check and LLM-as-a-judge evals, Microsoft's ASSERT tool for generating test sets, and DSPy prompt optimization that lets a cheap model satisfy a spec.
Evals for High-Stakes AI Agents — Doneyli De Jesus & Annabell Schäfer, Langfuse

Evals for High-Stakes AI Agents — Doneyli De Jesus & Annabell Schäfer, Langfuse

A hands-on workshop from Langfuse on evaluating AI applications where mistakes are costly. Using a banking assistant as the running example, Annabell Schäfer and Doneyli De Jesus walk through the AI engineering loop: tracing with PII masking, building datasets, turning domain-expert comments into failure modes, mixing LLM-as-a-judge and code evaluators, and CI gates that block prompt changes when scores drop.

CoreWeave Fully Connected 2026 Keynote: Introducing CoreWeave Forge | Built for Adoption

CoreWeave Fully Connected 2026 Keynote: Introducing CoreWeave Forge | Built for Adoption

CoreWeave's Fully Connected 2026 Day 1 keynote centers on the AI loop of run, observe, curate, improve and evaluate, and the launch of CoreWeave Forge. It covers production agent operations, agent observability and RL rollouts, Vera Rubin NVL72 and the Vera CPU, and enterprise evaluation practices from Capital One, Caterpillar and Cognition.

Paving the Road to Production: Governed Enterprise AI Agents — Harish Gaggar, Credit Karma

Paving the Road to Production: Governed Enterprise AI Agents — Harish Gaggar, Credit Karma

Harish Gaggar of Intuit Credit Karma walks through an internal paved path for taking enterprise AI agents from experiments to production. The talk covers portal-based registration and provisioning, a centralized authenticated MCP gateway with custom reviewed MCP servers, gateway monitoring with OpenTelemetry, Tempo, Prometheus, and Grafana, LangGraph workflows with policy checks and human approval, durable memory through threads and checkpoints, agent tracking and evaluation records, PII filtering, and context optimization for token reduction.

The Death of the Code Review: What the Data Actually Says — Laurie Voss, Arize AI

The Death of the Code Review: What the Data Actually Says — Laurie Voss, Arize AI

Agents have multiplied code output, but human review cannot keep pace, and reviewer effectiveness collapses past roughly 400 lines. This talk by Laurie Voss surveys what OpenAI, METR, Cognition, Cursor, GitHub, Carlini, and Bun are doing about it, from mergeability benchmarks and multipass automated review to prompt injection and production monitoring as the last line of defense.

Building the Safety Layer for AI Agents

Building the Safety Layer for AI Agents

Raindrop is building the safety layer for AI agents, detecting and preventing production failures like hallucinations and failed tool calls. The company addresses the paradox that as agents become more capable, they introduce greater complexity and more ways for things to go wrong. Their new Raindrop Simulations product catches critical failures in CI before they ever reach production, democratizing a capability previously limited to large AI labs.