Large language models

Why Diffusion Will Win AI Inference with Inception Co-Founder and CEO Stefano Ermon

Why Diffusion Will Win AI Inference with Inception Co-Founder and CEO Stefano Ermon

Stefano Ermon, co-founder and CEO of Inception, discusses his company's radical bet on diffusion models to overcome the hardware and latency bottlenecks of autoregressive LLMs. He explains how parallel token generation in diffusion offers superior inference scaling and GPU utilization, expanding beyond images to discrete text and code generation. Ermon shares insights into Inception’s Mercury models, real-world applications like voice agents, the custom software stack required, and why efficiency will define the next era of AI competition.
The Search Engine for the Agentic Web — Will Bryk, Exa

The Search Engine for the Agentic Web — Will Bryk, Exa

Exa's CEO, William Bryk, discusses the impending AI search boom, predicting machines will soon outpace human searches dramatically. He explains Exa's evolution from a consumer search engine to an API for AI agents, driven by the realization that LLMs need external, 'perfect' retrieval to overcome the limitations of traditional search and combat societal misinformation. Exa leverages neural networks, embeddings, and customized features to provide fast, accurate, and cost-efficient information, with plans for a private data marketplace, aiming to deliver 'a year of research in a second' for AI agents and foster a deeply informed society.

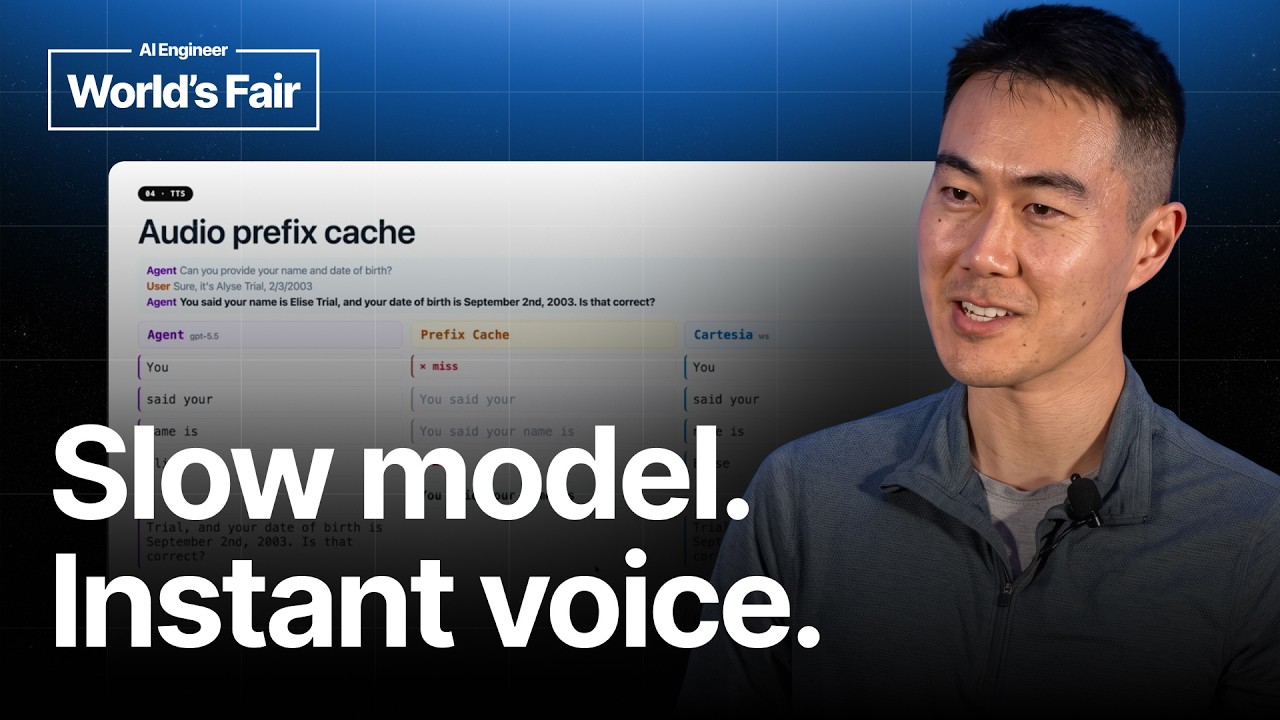
Realtime Voice Agents with Frontier Intelligence — Bohan Li, EliseAI

Realtime Voice Agents with Frontier Intelligence — Bohan Li, EliseAI

Bohan Li of EliseAI unveils a sophisticated architecture for real-time voice agents that merges high intelligence with low latency, akin to a self-driving car's perception, planning, and control systems. Key innovations include a speculative transcriber combining fast streaming with accurate contextual correction, background agents for offloading LLM tool calls and enabling eager generation, and a clever prefix cache for speech synthesis that seamlessly blends pre-cached audio with dynamically generated speech to mask underlying processing delays.

When Talking Becomes the Main Way We Use Computers — Pavan Muddireddy

When Talking Becomes the Main Way We Use Computers — Pavan Muddireddy

Mistral AI's Voxtral suite represents a significant advancement in voice AI, moving beyond traditional cascaded systems towards more integrated and efficient audio understanding and generation. Pavankumar Reddy Muddireddy of Mistral AI details Voxtral Chat's audio-native architecture, which directly feeds continuous audio embeddings into a text LLM for rich context. He explains Voxtral TTS's use of continuous latents and flow matching for high-fidelity speech synthesis. The discussion also covers critical challenges like speaker diarization, the use of Direct Preference Optimization (DPO) to correct model hallucinations, and the enduring relevance of specialized model cascades in real-world enterprise deployments for their adaptability and control, emphasizing that voice typically thrives alongside a screen, not in isolation.

OpenAI’s GPT-6 Astra (Ep. 1026 with Jon Krohn)

OpenAI’s GPT-6 Astra (Ep. 1026 with Jon Krohn)

Jon Krohn examines OpenAI's GPT-6 Astra, its new flagship model. He delves into its state-of-the-art capabilities across computer use, coding, abstract reasoning, and scientific discovery, including its role in finding zero-day vulnerabilities. Krohn also critically analyzes the AGI claims surrounding Astra, comparing its performance and safety features with competitors like Anthropic's Fable 5.1, offering a balanced perspective on its significance.

500 Skills, Zero Fine-Tuning: LinkedIn's Playbook for AI Agents — Ajay Prakash, LinkedIn

500 Skills, Zero Fine-Tuning: LinkedIn's Playbook for AI Agents — Ajay Prakash, LinkedIn

LinkedIn revolutionized its approach to AI agents by addressing the inherent limitations of LLMs in complex enterprise environments. Facing issues like hallucinations due to a lack of internal context, they developed a system of "playbooks" — structured, self-contained instructions published as tools. To scale beyond typical MCP limitations, they introduced three meta-tools (search, get schema, execute), enabling agents to dynamically discover and utilize thousands of internal tools and playbooks. This self-improving, context-aware infrastructure empowers agents to handle tasks from incident response to code generation, significantly boosting developer productivity and ensuring reliability.