Grpo

Small Models, Big Results: Training a Finance Agent for Under $500 — Charles Dickens, Snorkel AI

Small Models, Big Results: Training a Finance Agent for Under $500 — Charles Dickens, Snorkel AI

Snorkel AI and UC Berkeley's Sky Computing Lab show that a 4B Qwen3 model, trained with reinforcement learning for under $500 using the rLLM framework, beats its 235B sibling on expert-validated financial question answering built from SEC 10-K filings. The talk covers the FinQA dataset construction and verification, common failure modes of frontier models, transfer to multi-table and general tool-use tasks, and ablations showing that simple data and binary rewards outperform more elaborate setups, since the real bottleneck is disciplined tool use rather than reasoning depth.
Beating RL With Reflection: GEPA and Optimize Anything — Lakshya A. Agrawal, GEPA

Beating RL With Reflection: GEPA and Optimize Anything — Lakshya A. Agrawal, GEPA

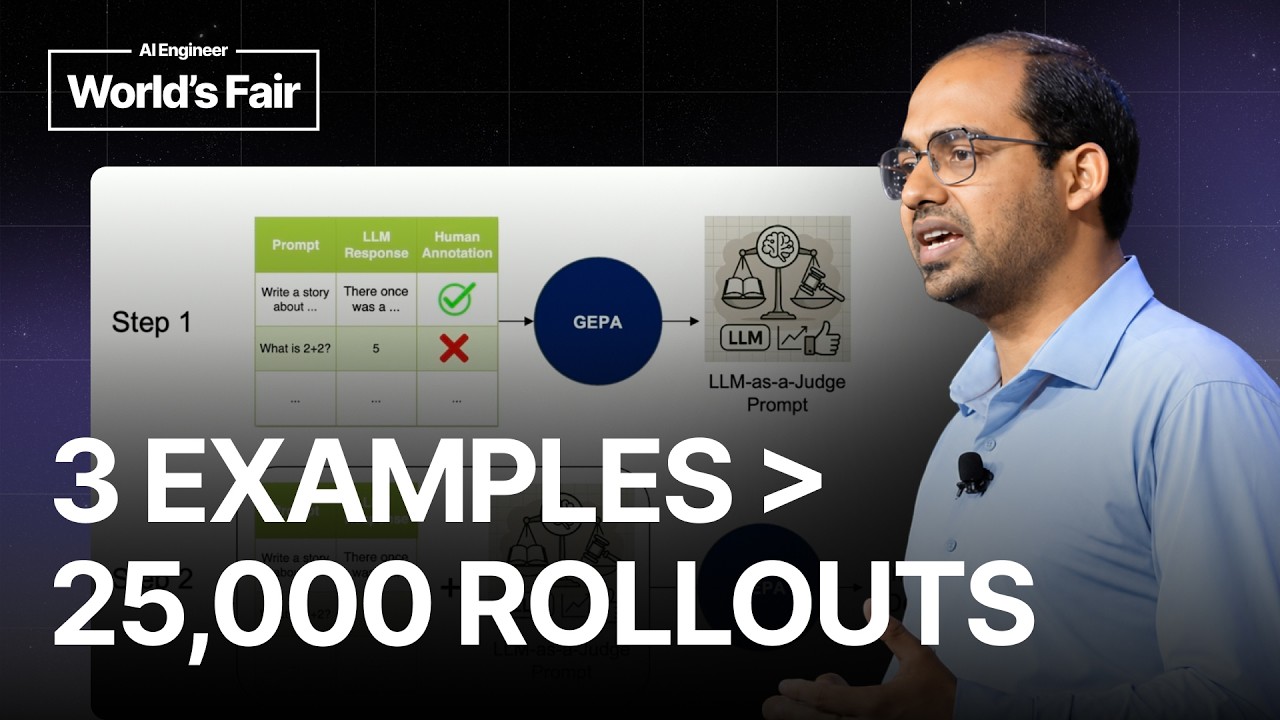
Lakshya Agrawal, creator of GEPA and a PhD student at UC Berkeley's Sky Computing Lab, presents reflective optimization as an alternative to scalar-reward reinforcement learning. GEPA lets a model read full rollout traces, including reasoning, tool calls, and error messages, and rewrite prompts from that feedback, with a Pareto candidate pool guarding against local optima. The talk covers the GEPA vs. GRPO sample-efficiency comparison, domain-knowledge discovery, the Optimize Anything API for text-based artifacts like code, harnesses, and skills, and production results from Databricks, Snorkel, and others.