Beating RL With Reflection: GEPA and Optimize Anything — Lakshya A. Agrawal, GEPA
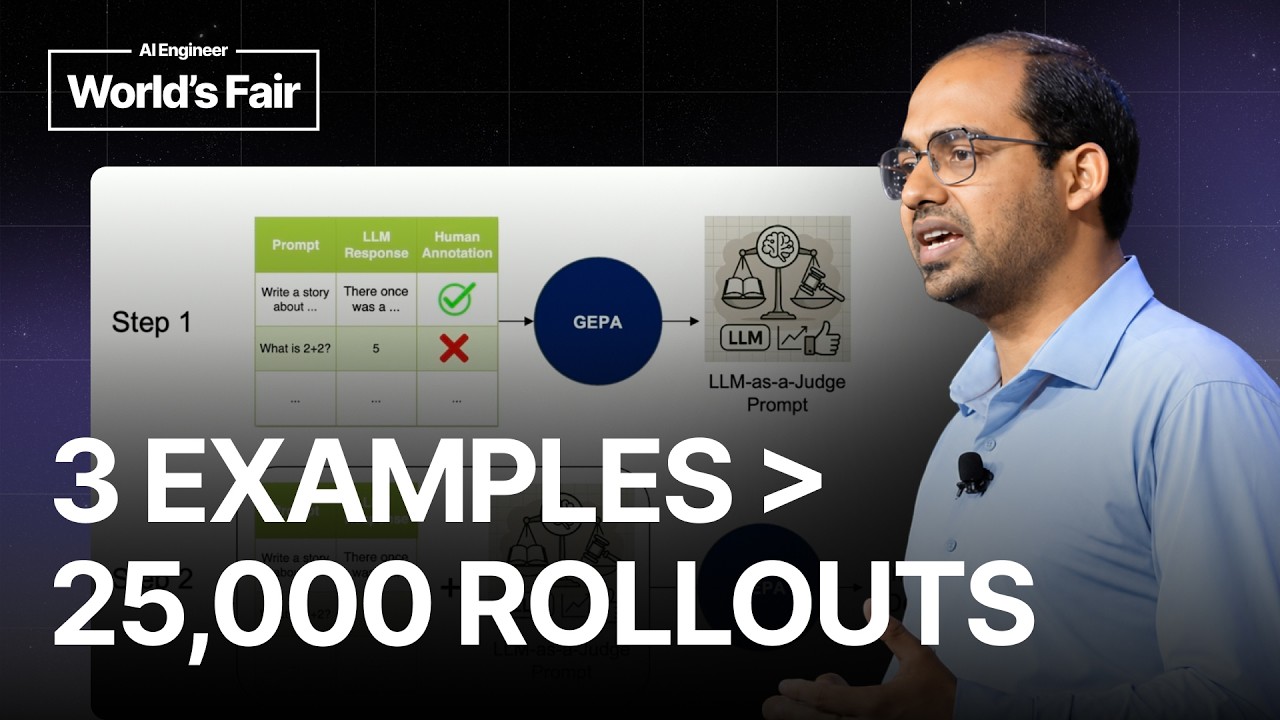
Lakshya Agrawal, creator of GEPA and a PhD student at UC Berkeley's Sky Computing Lab, presents reflective optimization as an alternative to scalar-reward reinforcement learning. GEPA lets a model read full rollout traces, including reasoning, tool calls, and error messages, and rewrite prompts from that feedback, with a Pareto candidate pool guarding against local optima. The talk covers the GEPA vs. GRPO sample-efficiency comparison, domain-knowledge discovery, the Optimize Anything API for text-based artifacts like code, harnesses, and skills, and production results from Databricks, Snorkel, and others.