Feature

The AI Memory Wall: Why LLMs & AI Accelerators Hit a Bottleneck

The AI Memory Wall: Why LLMs & AI Accelerators Hit a Bottleneck

A walkthrough of the memory wall, explaining why raw chip compute growth has not translated into proportional AI workload speedups. It covers arithmetic intensity, the roofline model and ridge points for the B200 GPU, why LLM decode is memory-bound while prefill is compute-bound, and how batching and continuous batching shift workloads toward higher efficiency.
Teach Your Agent to Prove It's Done — Nick Nisi & Zack Proser, WorkOS

Teach Your Agent to Prove It's Done — Nick Nisi & Zack Proser, WorkOS

Nick Nisi and Zack Proser from WorkOS explore how to move "Beyond Done" with AI agents, ensuring their work is truly complete and reliable. They demonstrate building robust verification loops using custom CLIs, browser tools, and LLM judges, allowing agents to self-check and self-correct, preventing costly mistakes and accelerating development velocity for a technical audience.

AI Safety Fact vs. Fiction | YC Paper Club

AI Safety Fact vs. Fiction | YC Paper Club

This episode of Paper Club addresses AI safety from a scientific perspective, contrasting it with recent media sensationalism. Stanford professors Clark Barrett and Mykel Kochenderfer discuss how automated reasoning can mathematically prove code security, how aircraft stress-testing methods are being adapted for language models, and the potential need for an NTSB-like agency for AI, highlighting the real-world engineering challenges and solutions for AI safety.

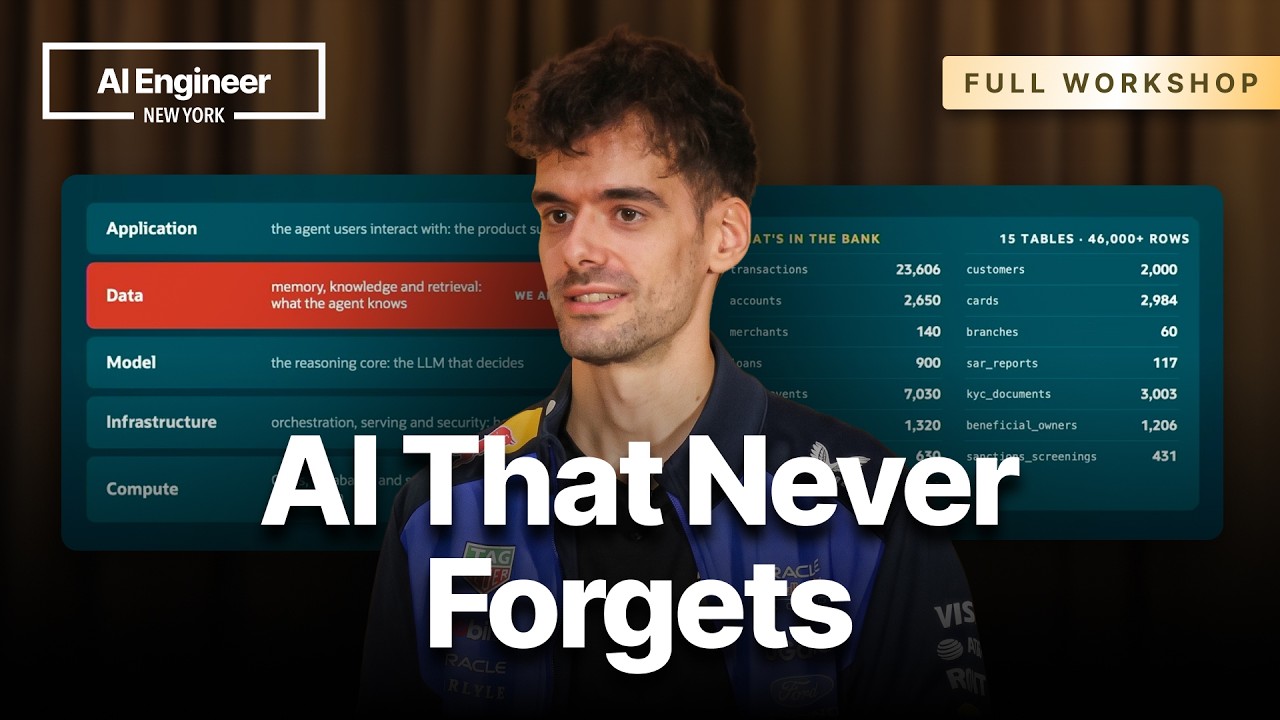
Memory-Aware Agent Harnesses for Anti-Money Laundering — Nacho Martinez, Oracle

Memory-Aware Agent Harnesses for Anti-Money Laundering — Nacho Martinez, Oracle

Nacho Martinez argues that the model is fixed while the harness (agent loop, memory, context engineering, tools and skills, continual learning) is where engineers can make real gains. He walks through the agent stack and applies it to an autonomous AML agent that flags suspicious bank transactions, then demonstrates the workshop environment and answers questions on memory design, skill retrieval, caching, and hybrid search.

High Taste Testers: OpenAI Shipped Everything. What Actually Works?

High Taste Testers: OpenAI Shipped Everything. What Actually Works?

A roundtable of AI power users reviews OpenAI DevDay and asks what actually works in daily use. Topics include personal assistants and their trust, permission, and safety trade-offs; durable agent state and remote execution; the Jev decision model and calibrated classification; model preferences across Anthropic, OpenAI, xAI, Meta, and open models; subagents and context management; and the gap between impressive capabilities and products that hold up.

Why AI Can Write Code But Can’t Keep It Running (Yet)

Why AI Can Write Code But Can’t Keep It Running (Yet)

Grepr CEO Jad Naous talks with a16z's Martin Casado about how coding agents have changed a 10-person engineering team, with projects that once took six months now finishing in about ten days. They examine whether AI can reason about and troubleshoot production distributed systems, why operations is a harder problem than code generation, and where AI adoption is likely to go next.