Guardians of the State: An Air-Gapped AI Fortress for Consumer Data — Rachna Srivastava, DFPI
Rachna Srivastava discusses building a legally defensible AI system for financial fraud detection, emphasizing that generative AI has eroded traditional trust. Her team at DFPI engineered an offline, hardware-secured data pipeline using Kafka, Spark, and semantic routing to ensure explainability, reproducibility, and auditability. They implemented a one-way data diode for secure learning and Apache Iceberg for time-travel queries, asserting that "trust is a physical property" built into the system's core.
Rachna Srivastava, from the California Department of Financial Protection and Innovation (DFPI), outlines a critical shift in how trust must be engineered into systems given the advent of generative AI. With AI’s capability to clone voices, create synthetic faces, and impersonate individuals at scale, the traditional foundations of trust based on sensory verification have collapsed, making deception cheap and widespread. The DFPI’s mandate is to protect 39 million Californians from financial fraud, a process that culminates in legal enforcement. This necessitates building AI systems that are not merely effective but also undeniably credible, explainable, reproducible, and auditable at every stage, as all generated evidence must withstand rigorous scrutiny from defense attorneys in court.
Challenges with Conventional Security Measures
Traditional security paradigms, such as encryption (data at rest or in transit), proved insufficient for DFPI’s high-stakes environment. While encryption is robust, machine learning models require data to be decrypted into plain text in memory, exposing it to prompt injection attacks. Private endpoints, despite offering isolation, are cloud-provider owned, leaving data vulnerable to access under the Cloud Act without user notification. Furthermore, certifications like FedRAMP, ISO, and SOC 2 are dismissed as mere ‘paper,’ given the recurring failures of compliant organizations. For the level of assurance required for courtroom evidence, an entirely offline solution was deemed essential.
The Initial Failure and the Data Engineering Revelation
Their first attempt mirrored a common industry approach: deploying an open-source model in an isolated GPU environment with system prompts and guardrails, then feeding it live data. This system ‘collapsed in 2 hours.’ The team initially suspected the model’s quality but soon realized the fundamental flaw: treating the ‘machine learning model as a magic box instead of as a data pipeline.’ Expecting the model to process raw, messy data led to hallucinations and poor performance. This pivotal insight led to the conclusion that ‘most of the data problem in AI are data engineering problem wearing AI mask.’ Consequently, their refined architecture separated concerns using specialized tools: Kafka for data ingestion, Spark for data processing, and an LLM for reasoning.
Robust Data Pipeline for Ingestion and Processing
- Kafka for Data Ingestion and Reproducibility: Kafka was implemented to handle inconsistent data ingress, particularly during fraud spikes, buffering traffic for consistent downstream consumption. It ensured sequential ordering of events, which is crucial for reconstructing complex fraud timelines. Critically, Kafka’s ability to ‘move the checkpoint to the point at which the decision was made’ and replay events provides irrefutable, reproducible proof for legal proceedings.
- Spark for Data Cleaning and Pre-processing: Recognizing the heterogeneity and messiness of financial data (e.g., ten different bank statement formats, audio files, screenshots), Spark was utilized for extensive data cleaning and pre-processing on CPU clusters. This preparation of ‘condensed clean data’ before it reached the model’s memory drastically improved the model’s performance, allowing the same model to yield significantly better results and identify novel connections.
Hardware-Level Security for Sensitive Information
To protect sensitive PII (Personally Identifiable Information) like credit card and social security numbers within the clean data, a ‘cryptographic vault’ was developed. This system employs a SHA-256 cryptographic algorithm with a Hardware Security Module (HSM). Data is converted into cryptographic hashes, with the crucial encryption key ‘physically attached to our server rack.’ This design ensures that any data compromise would require physical intrusion, emphasizing the principle: ‘If the stakes are really high, trust hardware over software.’
Optimizing Model Inference with Semantic Routing
Initially, a single state-of-the-art model performed all tasks (summarization, entity extraction, fraud detection), akin to a ’neurosurgeon tak[ing] the blood pressure of every single patient’ – an inefficient use of resources within a constrained, isolated environment. To optimize, a ’triage nurse or semantic router’ was introduced. This component analyzes incoming data and directs requests to the ‘smallest possible model which is capable of processing that request.’ This architectural enhancement enabled over 80% of tasks to be handled by smaller, faster, and cheaper models, tripling throughput without adding new GPUs and reducing the cost per request by nearly 70%.
Secure Continuous Learning via One-Way Data Diode
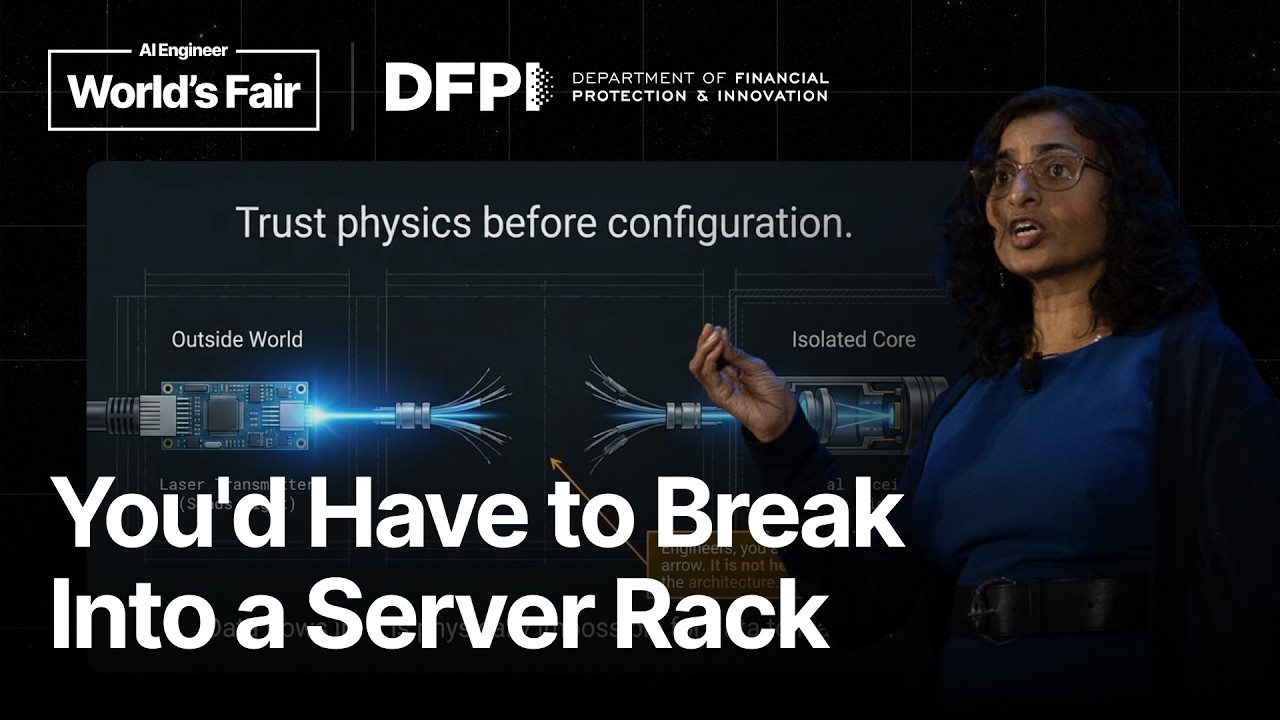
A major challenge was enabling the system to learn and adapt to evolving threats without creating security vulnerabilities. The team rejected software firewalls, citing their susceptibility to misconfiguration and subsequent exploitation. Instead, a physical ‘one-way data diode’ was implemented – a fiber optic cable ‘physically cut into half.’ One half, connected to the internet, contains a laser transmitter that sends data to the second half, which has only a laser receiver connected to their internal system. Crucially, there is ’no laser transmitter from our end to the outside world,’ making data exfiltration ‘physically impossible’ and guaranteeing 100% security against outbound leaks. All incoming data first lands in a ‘quarantine zone’ for validation via Spark jobs before entering the production layer.
Reproducibility with Time-Travel Data Stores
For long-term courtroom defensibility, the system leverages Apache Iceberg, an ‘immutable time traveled queryable data store.’ This allows the team to ’travel the Apache Iceberg, go to the point at which the decision was made and get the state of the system at that moment from the database’ years later, providing a precise, auditable snapshot of the system’s state as proof in court.
The Philosophy: Trust as a Physical Property
The overarching philosophy is that ’trust is not a policy. Trust is a physical property of the system.’ It must be meticulously engineered into the hardware, physics, and architecture from the outset. This robust, end-to-end secure architecture, where data remains protected until the final user interaction, is presented as ’the architecture of the future,’ applicable across critical domains such as healthcare, banking, and legal services. The ultimate measure of success is building solutions that are inherently trusted when they are needed most, rather than focusing solely on models or benchmarks.