How MiniMax M3 Was Built: Sparse Attention and Native Multimodality — Olive Song
Olive from MiniMax walks through MiniMax M3, an open-weight model built for agentic coding, 1M token context, and native multimodality from the first training step. The talk centers on MSA, a GQA-aware block-level sparse attention design co-developed with GPU infrastructure in mind, and on why training text and vision together from scratch beats adding vision later.
Overview
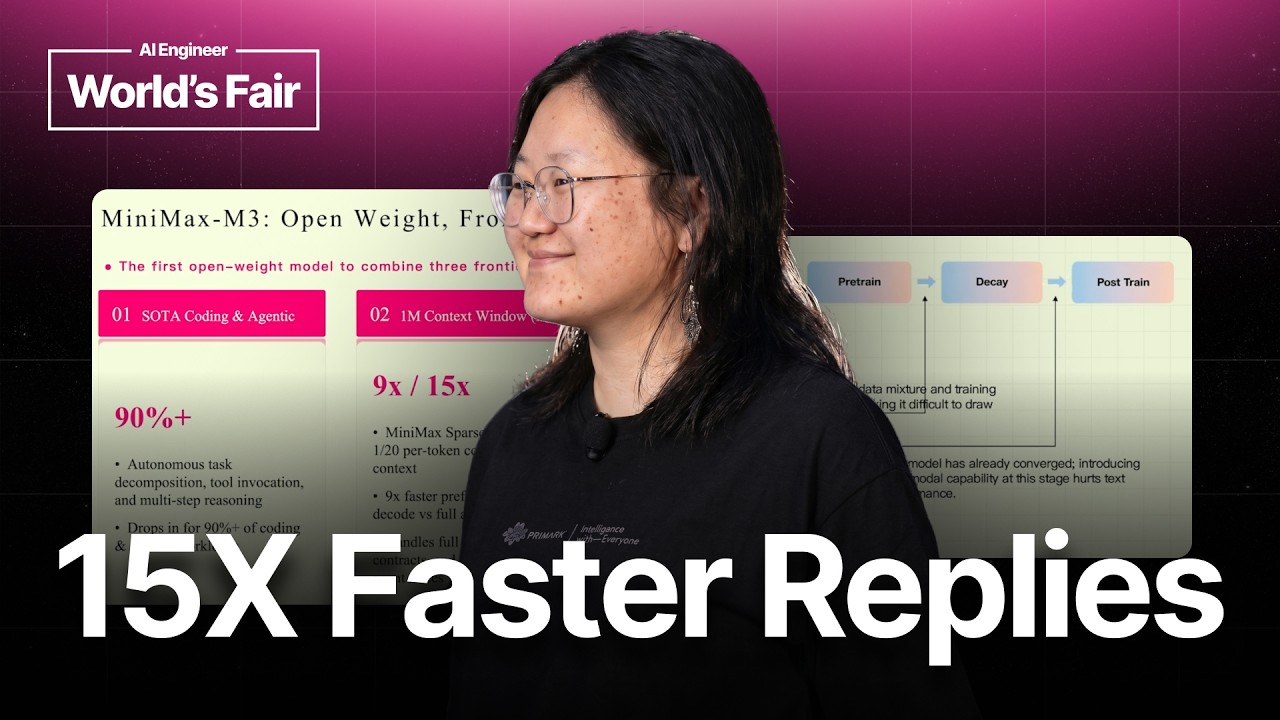
Olive, a reinforcement learning researcher at MiniMax, presents MiniMax M3 as the first open-weight model to combine three frontier capabilities: agentic coding, a 1 million token context window, and native multimodality. Her talk covers two linked design decisions: MSA, a sparse attention mechanism that makes long context affordable, and a training recipe that introduces vision from the first step instead of attaching it after the language model has formed.
Three Pillars of M3
The first pillar is agentic coding. Olive says the model can perform automatic task decomposition, work inside coding agents, and handle a large share of everyday coding work. The second is the 1M token context, which she frames as enabling real long-form interaction, such as working over full code bases. The third is native multimodality. Because vision was present from scratch, she argues the model understands text and images jointly from the start, which opens the door to applications like computer-use agents. She claims MSA delivers roughly 9x faster prefill and 15x faster decoding than full attention.
Design Philosophy: Algorithm and Infrastructure Co-design
Olive states a core principle: a simpler architecture scales better. The team treats algorithm and infrastructure as one problem rather than designing the algorithm in isolation and then optimizing it. That framing explains most of the choices that follow.
How MSA Works
MSA has two branches. The index branch is a lightweight full-attention computation with four query heads and one key head. It is trained with a KL loss to match the attention scores of the main branch, and its job is to identify the tokens or blocks with the highest attention scores. The sparse branch then attends only to that selected subset, using the blocks chosen by the index branch to determine which keys and values are needed.
Why DeepSeek’s DSA Did Not Fit
Olive describes DSA as a strong design that is heavily tuned to DeepSeek’s architecture, particularly its combination of MQA and a large head dimension. Moving to GQA, which is more common in practice, makes direct reuse problematic for three reasons:
- Diversity loss: GQA has multiple KV heads meant to offer diverse views. If they all reuse one token selection, they attend to exactly the same tokens, cancelling out the diversity GQA is designed to provide.
- Memory access: In MQA, the KV layout is effectively one contiguous read (for example, 1 x 512). In GQA the same total dimension is split across heads (for example, 4 x 128), requiring multiple independent, non-contiguous reads. That increases overhead and lowers the compute-to-memory access ratio.
- Top-k cost: Token-level selection requires top-k over many candidates. Top-k has data dependencies that are hard to parallelize on GPUs, so selection and merging add significant overhead.
What MSA Changes
On the algorithm side, MSA stops merging the outputs of the index branch heads into one shared selection. Each KV head keeps its own selection, so different KV heads can attend to different token sets, preserving GQA’s diversity.
On the infrastructure side, MSA moves from token-level selection to block-level retrieval. This reduces the number of candidates, lowers top-k and merge overhead, and produces more hardware-friendly memory access with a better compute-to-memory ratio. Olive asserts that this does not introduce a significant performance drop. She also mentions custom kernels for both training and inference, which she deliberately skips, though she identifies them as what makes the design practical.
Training With Vision From Step Zero
Olive frames the central challenge as introducing multimodal capability without hurting core text performance. Standalone VL models have limited application scope, but combining vision with text during training is difficult. The team compared three strategies:
- Adding multimodal data after the pre-training decay stage (a CPT-style approach). By then the model has largely converged, and the new data tends to interfere with and degrade text capability.
- Introducing multimodal data before the decay stage, after a number of text tokens have been seen. Results were highly sensitive to data mixture and hyperparameters such as learning rate, and a setting that helped in one run did not generalize to another. Large-scale pre-training does not allow these parameters to be tuned freely for multimodal data.
- Native multimodal training from scratch, where vision is present from the beginning rather than added after the text structure has formed. Under the same text token budget, Olive reports that this almost does not hurt text capability.
What the Attention Maps Reveal
One of the more interesting findings comes from attention analysis. In CPT-style multimodal models, text tokens pay very little attention to visual tokens, and the visual regions appear mostly dark in the attention map. Olive reads this as evidence that modalities are not truly integrated. In native multimodal models the map looks far more integrated, with no clear separation between text and visual tokens, suggesting the model learns to fuse the two more naturally from the start.
Architecture and 3D Attention in the ViT
The architecture is relatively standard. A ViT processes images or video into visual tokens, which replace the image placeholders in the text sequence. Visual and text embeddings are then fed jointly into the language model.
The key architectural finding is that 3D attention inside the ViT substantially improves visual understanding. Standard ViT attention operates within each image or frame, so patches from different video frames never interact at the encoder stage. With 3D attention they can attend to each other directly, which strengthens temporal and cross-frame modeling. The gains also transfer to some image benchmarks, which Olive takes as evidence that the improvement is a stronger general visual representation rather than a video-specific trick. Extending 3D attention to an unlimited number of frames creates system and load-balancing problems, so the team found that four frames offered the best trade-off between performance and efficiency.
Takeaway
Olive’s central message is that multimodality should be integrated into the model’s foundation rather than appended to it. The combination of a simpler sparse attention design shaped by GQA and GPU realities, and a native multimodal training recipe, is presented as what allows MiniMax M3 to be both long-context and visually capable without sacrificing text quality.