Stop Evaluating Models Like It's the 50s - Alejandro Vidal, Mindmakers
This talk introduces the transformative potential of Item Response Theory (IRT), a psychometric model, for evaluating AI models. It addresses the limitations of current evaluation methods by demonstrating how IRT can precisely measure model intelligence, audit and optimize benchmarks, detect data leakage, implement adaptive testing, identify item bias, and even fingerprint models based on their error patterns, opening new avenues for understanding and improving LLM capabilities.
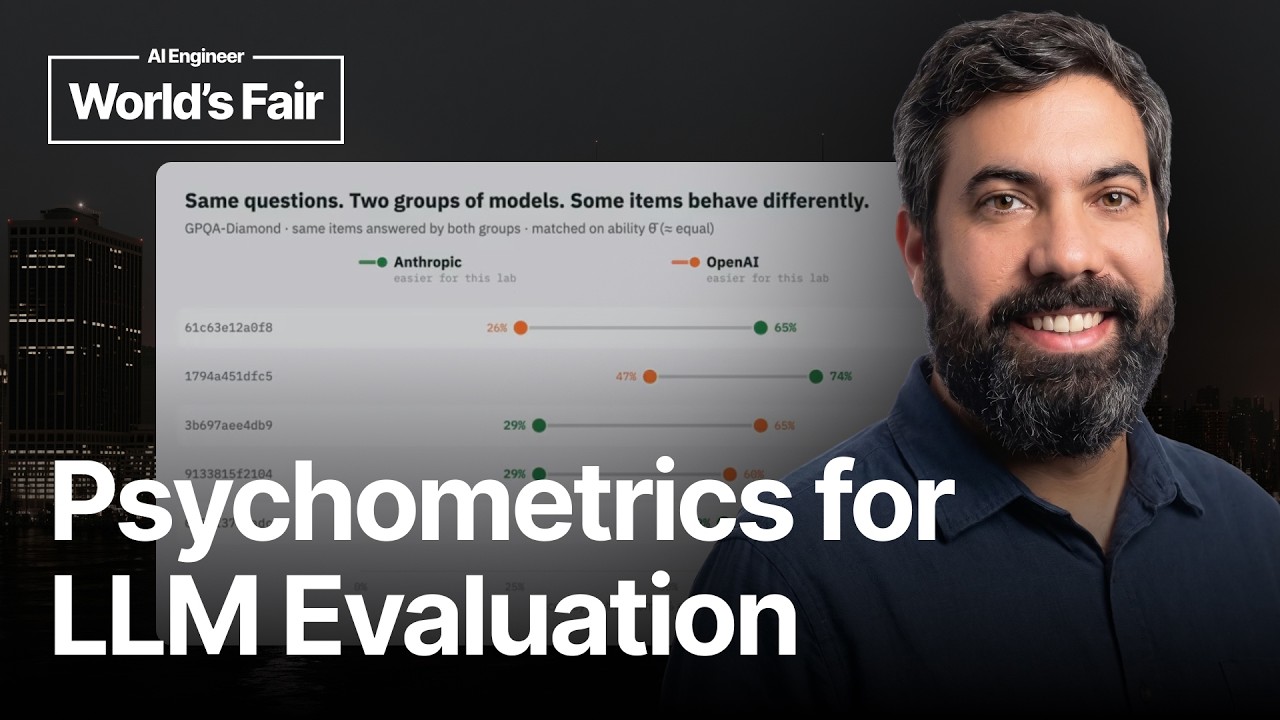
This talk by Alejandro Vidal of Mindmakers introduces the application of psychometrics, specifically Item Response Theory (IRT), to improve the evaluation of AI models, particularly LLMs. He argues that current evaluation methods, based on Classical Test Theory (CTT), merely count right answers and assume all questions are equally important, which is a simplistic and outdated approach.
Limitations of Classical Test Theory (CTT)
- Equal Weighting: CTT assumes every question in a benchmark carries the same importance, ignoring variations in difficulty or quality.
- Inaccurate Intelligence Estimation: Simply counting correct answers can be misleading, as models might answer easier questions correctly without possessing a higher overall “intelligence.”
Introduction to Item Response Theory (IRT)
Vidal proposes leveraging IRT, a sophisticated psychometric model used in standardized tests like the SAT and GRE, to address these limitations. IRT treats each question (or “item” in psychometrics) as an individual variable with distinct properties.
Key IRT Parameters:
- Item Difficulty (B parameter): For each question, IRT estimates a difficulty level. A function maps an LLM’s intelligence to the probability of answering that question correctly. B represents the point where a model has a 50% chance of getting the item right. These B values are normally distributed, aiding interpretation (e.g., B=0 indicates an average difficulty item).
- Model Intelligence (Theta parameter): IRT estimates an intelligence level for each model. This is represented as a black dot on a shared scale, and questions to its right (more difficult than the model’s theta) are more likely to be answered incorrectly.
- Item Discrimination (A parameter): This parameter measures how well an item differentiates between models of different intelligence levels. High discrimination items have steeper functions, meaning they are very effective at distinguishing between slightly more or less intelligent models. Items with low or negative discrimination (where more intelligent models get the answer wrong) are considered problematic.
IRT estimates an LLM’s intelligence by iteratively combining the information from each item’s curve, resulting in a likelihood distribution for Theta, providing valuable confidence intervals absent in CTT.
Advantages of IRT over CTT
Using real data from Epoch.ai, Vidal demonstrates how IRT provides a far more nuanced understanding than simple accuracy scores. For example, while two models (Claude Opus 4.1 and Gemini 3 Pro) might have very similar raw correct answers (245 vs. 247 out of 337), IRT reveals a nearly one-standard-deviation difference in intelligence, indicating Gemini 3 Pro is significantly more capable, likely by answering harder questions.
Practical Applications of IRT in AI Evaluation
-
Benchmark Auditing and Improvement: IRT allows for the identification of problematic items within a benchmark.
- Noisy/Useless Items: Items with low discrimination (A parameter close to zero).
- Negative Correlation: Items where better models perform worse, indicating fundamental flaws.
- Mislabeled Answers: The speaker provided an example of a question asking for “passengers” where the gold answer included “crew,” highlighting common labeling errors that IRT can expose.
-
Benchmark Optimization and Reduction (Adaptive Testing): By selecting only the most informative items (those with high discrimination), benchmarks can be significantly shrunk while maintaining strong correlation with original rankings. A real-world example showed a ~5x reduction in items while preserving 99% rank correlation. This saves tokens, time, and money.
- The talk also noted that well-designed benchmarks like GPQA already have highly discriminative and non-overlapping items, making random selection less detrimental.
-
Detecting Data Leakage and Contamination: By analyzing residuals (the difference between expected and actual answers for each item), IRT can identify unexpected behaviors.
- Outliers: Models performing unexpectedly well or poorly on specific questions. While not definitive proof of overfitting, it’s a strong indicator that warrants further investigation.
- Inconsistent Behavior: Identifying models whose performance is highly inconsistent across items that should be predictable based on their estimated intelligence, potentially signaling issues with the inference platform or quantization.
-
Adaptive Testing for Benchmark Protection: To protect valuable benchmarks from leakage or training contamination, IRT enables adaptive testing:
- Anchor Set: A core set of representative items shared with all models/organizations.
- Fingerprint Sets: Unique sets of highly difficult items shown only to specific organizations.
- By monitoring residuals on these fingerprint sets over time, abnormally low residuals (i.e., models consistently getting difficult, unique-to-them questions right) can signal data leakage or explicit training on the benchmark.
-
Detecting Item Bias (Differential Item Functioning - DIF): Similar to detecting bias in human tests, IRT can assess if an item behaves differently for distinct groups of models (e.g., open-weight vs. closed-weight models). By comparing item curves for these groups, items showing significant discrepancies can reveal underlying biases or characteristic performance differences.
-
Model “DNA” / Fingerprinting: Using the correlation matrix of model residuals, IRT can create a “fingerprint” for each model. This allows for:
- Relationship Mapping: Identifying models from the same lab or family (e.g., different versions of Llama, DeepSeek distillations) that exhibit similar error patterns.
- Distillation Detection: Identifying if a model is a distillation of another, even without explicit consent, by observing high residual correlations.
- Version Tracking: Distinguishing different versions or effort levels of the same model.
Future Research and Applications
Vidal highlights several promising avenues for future work:
- Multidimensionality and Hierarchical Models: Exploring different skill levels for various tasks within LLMs.
- Merging Benchmarks: Improving estimations by combining information from multiple benchmarks using IRT.
- Additional Signals: Incorporating other relevant data like latency or token usage into psychometric models.
- Measuring Alignment and Interpretability: Applying psychometric models to quantify and understand LLM alignment, potentially linking with mechanistic interpretability.
This talk serves as an invitation to the ML and AI community to adopt principles from a century of psychometric research to build more robust, efficient, and informative evaluation systems for LLMs.