Tokenless

Interactive discovery

Explore the topic map

Follow the connections between themes, people, and ideas across the Tokenless archive in an interactive topic modeling map.

Machine Learning

View All
Judge a Transaction by the Company It Keeps — Somya Rai & MD Sharique, EXL

Judge a Transaction by the Company It Keeps — Somya Rai & MD Sharique, EXL

EXL developed an advanced fraud detection system that augments XGBoost with Graph Neural Network (GNN) embeddings. Traditional tabular models struggle to capture fraud signals residing in transaction neighborhoods. The system's innovative design includes meticulous sampling strategies, disjoint monthly graph construction for leakage control, and a GraphSAGE architecture that aggregates mean, max, and standard deviation of neighbor features to detect subtle fraud patterns. Emphasizing explainability for regulatory compliance and analyst trust, it also features a highly optimized serving architecture achieving 3ms P99 latency, pivoting to edge prediction to reduce cache footprint from 60GB to 2-3GB. This led to a 27-33% relative lift in true positive rates and a projected $65 million incremental fraud capture.
From 15% to 90% GPU Utilization: Fix the Data Pipeline, Not the Model

From 15% to 90% GPU Utilization: Fix the Data Pipeline, Not the Model

Tarun Sunkaraneni from Amazon AGI shows how a multimodal SFT pipeline that spent about 85% of its time waiting on data was brought to roughly 90% GPU utilization. He walks through concurrency with asyncio and Ray actors, prefetching, zero-copy transfer via Ray's object store, and a network-card bottleneck that appears only at scale, and argues that the hardest part of training throughput is often keeping GPUs fed rather than optimizing the model.

Small Models, Big Results: Training a Finance Agent for Under $500 — Charles Dickens, Snorkel AI

Small Models, Big Results: Training a Finance Agent for Under $500 — Charles Dickens, Snorkel AI

Snorkel AI and UC Berkeley's Sky Computing Lab show that a 4B Qwen3 model, trained with reinforcement learning for under $500 using the rLLM framework, beats its 235B sibling on expert-validated financial question answering built from SEC 10-K filings. The talk covers the FinQA dataset construction and verification, common failure modes of frontier models, transfer to multi-table and general tool-use tasks, and ablations showing that simple data and binary rewards outperform more elaborate setups, since the real bottleneck is disciplined tool use rather than reasoning depth.

Artificial Intelligence

View All
Everyone Has the Same AI Models. Here's What Sets Agents Apart - Richmond Alake, Oracle

Everyone Has the Same AI Models. Here's What Sets Agents Apart - Richmond Alake, Oracle

Richmond Alake argues that after the control plane, agent architectures need an intelligence plane covering what an agent knows, remembers, is allowed to see, and how it improves. He draws on the WWII Midway codebreaking story to separate information from intelligence, then demos a governed agent using an ontology and semantic layer that answers correctly about 99% of the time with far fewer tokens than a naive agent. The talk also covers Oracle's agent memory package, deep data security, private inference, and fine-tuned decision models for memory routing.

Using Agents for Long-Horizon Financial Work — Aman Singh, Arca

Using Agents for Long-Horizon Financial Work — Aman Singh, Arca

Aman Singh, head of AI at Arca, explains how the firm is building an AI-native wealth management business in which agents run back-office work, monitor clients proactively, and coordinate multi-day workflows, while humans retain advisory relationships and trade execution. The discussion covers model selection through internal benchmarks, a model-agnostic custom harness with tiered routing, persistent memory for long-running tasks, deterministic and LLM-based guardrails, auditability by default, decision models for financial accuracy, and feedback loops that turn staff edits into evals.

THE $800B COMPUTE TRAP

THE $800B COMPUTE TRAP

Ben Lorica and Evangelos Simoudis work through Anthropic's S-1 filing, weighing its striking growth and improving unit economics against compute commitments, falling prices from open-weight models, and dependence on coding. They then examine SpaceX's emerging neocloud business and close with a debate over proposed frontier AI regulation, from self-improvement limits to independent testing and incident disclosure.

Technology

View All
Why Founders Are Betting Big on Factories, Mines, and Energy

Why Founders Are Betting Big on Factories, Mines, and Energy

Erin Price-Wright and Connor Love unpack the AD50 and the rebuilding of America's industrial base, covering how defense demand is financing manufacturing capacity for commercial markets, how AI is reshaping factory economics, how a new generation of founders applies lessons from SpaceX, Tesla, Anduril, and Palantir to mining, energy, and manufacturing, and why private capital is now willing to fund physical infrastructure before government demand is guaranteed.

Mark Cuban’s Plan to Make Healthcare Affordable

Mark Cuban’s Plan to Make Healthcare Affordable

Mark Cuban and Julie Yoo discuss how transparency, direct contracting, and AI could reshape healthcare economics, from Cost Plus Drugs and modular pod manufacturing to personalized medicine, the future of physicians, and advice for founders who want to use AI to learn rather than to stop thinking.

Exploits Now Beat Patches: Open Source Security in the AI Era - Patrick Smyth, Chainguard

Exploits Now Beat Patches: Open Source Security in the AI Era - Patrick Smyth, Chainguard

Patrick Smyth of Chainguard examines how frontier AI has compressed the time between vulnerability disclosure and exploitation, leaving 30-day remediation cycles obsolete. The talk covers AI-assisted attacks, waves of supply chain malware, four attack surfaces spanning malware, known CVEs, zero days, and side doors like CI/CD, developer laptops, and agent skills, and practical defenses including cooldown periods, faster CVE remediation, and signing artifacts with SLSA and Sigstore.


Recent Post

Multimodal & Embodied Intelligence (Pt 1), Panel on Multimodal AI: Progress, Pitfalls, Possibilities

Multimodal & Embodied Intelligence (Pt 1), Panel on Multimodal AI: Progress, Pitfalls, Possibilities

This session explored Multimodal and Embodied Intelligence, featuring talks on hybrid AI in robotics (classical vs. end-to-end), AI's role in healthcare (focusing on NCDs, deployment, and uncertainty modeling), and fundamental perception challenges in multimodal reasoning (using educational video QA and visual puzzles). A panel discussed the impact of foundation models, the blurred lines between AGI and human-like AI, critical deployment pitfalls (human factors, efficiency, architectural limits), and future directions, emphasizing task-specific models and the redefinition of 'foundation models.'

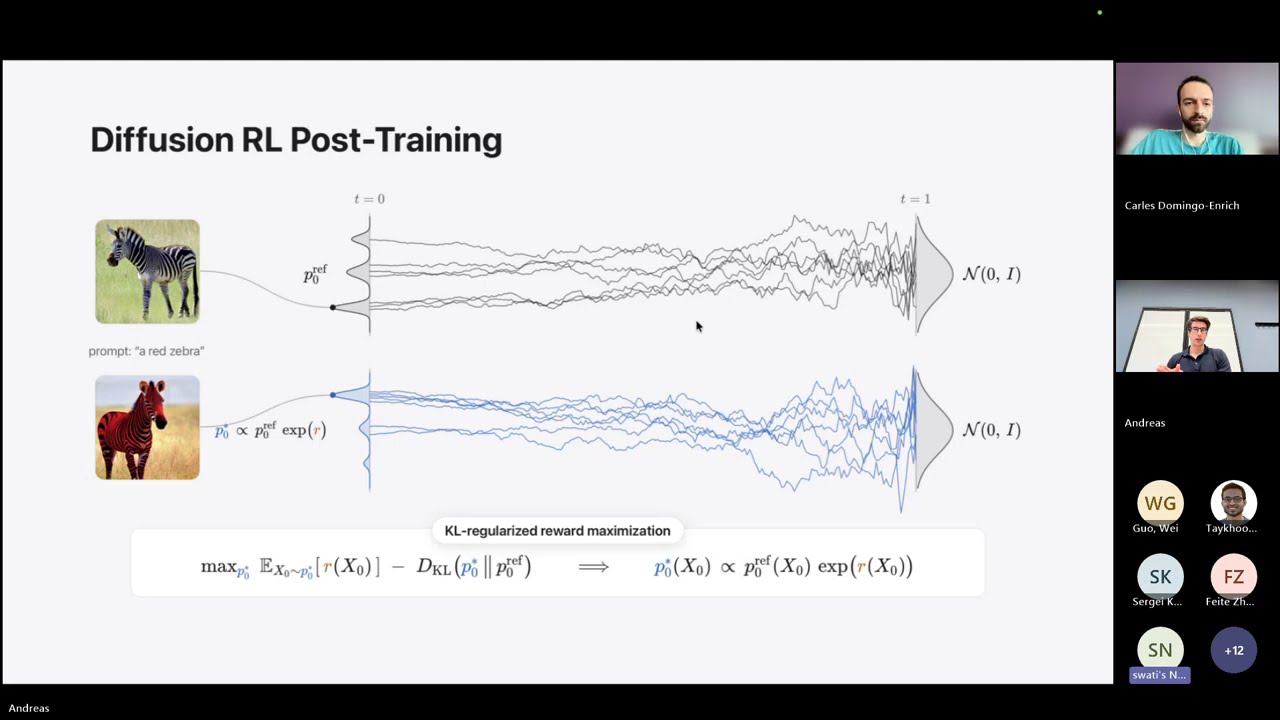
Reinforce Adjoint Matching: Scaling Diffusion RL

Reinforce Adjoint Matching: Scaling Diffusion RL

Andreas Bergmeister presents Reinforce Adjoint Matching (RAM), a novel method for scalable reinforcement learning post-training of diffusion models. RAM sidesteps the complexity of existing RL approaches by deriving a consistency loss that directly corrects the pre-training target with a reward signal, eliminating the need for costly SDE rollouts or reward gradients. This approach achieves superior performance and up to 50x faster convergence on challenging image generation tasks like complex composability, text rendering, and human preference alignment.

Grant Sanderson (@3blue1brown) – AI and the future of math

Grant Sanderson (@3blue1brown) – AI and the future of math

Grant Sanderson and Dwarkesh Patel discuss AI's rapid but uneven progress in mathematics, exploring whether AI can achieve true conceptual breakthroughs, the challenge of measuring creativity, and the long-term implications for human understanding and the future roles of mathematicians. They delve into the unique 'grindability' of math for AI training, the potential of formalization, and why AI currently struggles with 'theory of mind' in writing, offering advice for students navigating an AI-transformed world.

Sustainable Augmented Development • Kent Beck • YOW! 2025

Sustainable Augmented Development • Kent Beck • YOW! 2025

Kent Beck's presentation at YOW! Australia 2025 explores the transformative impact of augmented development ('the genie') on software engineering. He argues that AI shifts programming into an exploratory phase, requiring a re-evaluation of traditional practices. Beck introduces the concept of 'resting between the notes' to foster optionality over mere feature churn, and makes a compelling case for the increased value of junior developers as AI tools become powerful learning aids, emphasizing that 'nobody knows' the future but we must 'take our time' to adapt effectively.

Why Hardware-Software Co-Design Is AI's Real 100x: Dylan Patel of SemiAnalysis

Why Hardware-Software Co-Design Is AI's Real 100x: Dylan Patel of SemiAnalysis

Dylan Patel, founder of SemiAnalysis, details how software-hardware co-design drives 100x gains in AI performance, citing examples like DeepSeek's optimization for Nvidia Hopper and the architectural differences between OpenAI's sparse and Anthropic's dense models. He introduces InferenceX, a living benchmark tracking a 60x annual cost reduction in AI quality, and explains why the "CUDA moat" narrative is shifting. Patel also delves into the persistent compute crunch, the strategic rise of neoclouds, and Jensen Huang's efforts to foster a multipolar AI world to prevent hyperscaler dominance.

How KV Cache Speeds Up LLMs for Faster AI Models on GPUs

How KV Cache Speeds Up LLMs for Faster AI Models on GPUs

LLMs often slow down under heavy traffic due to inefficient GPU memory management during inference. This overview explains how KV cache and Paged Attention, implemented in VLLM, optimize memory usage across prefill and decode phases, significantly boosting LLM throughput, reducing latency, and improving GPU utilization through advanced context handling and specific tuning techniques like prefix caching and speculative decoding.

Stay In The Loop! Subscribe to Our Newsletter.

Get updates straight to your inbox. No spam, just useful content.