What AI gets wrong and what failure teaches us
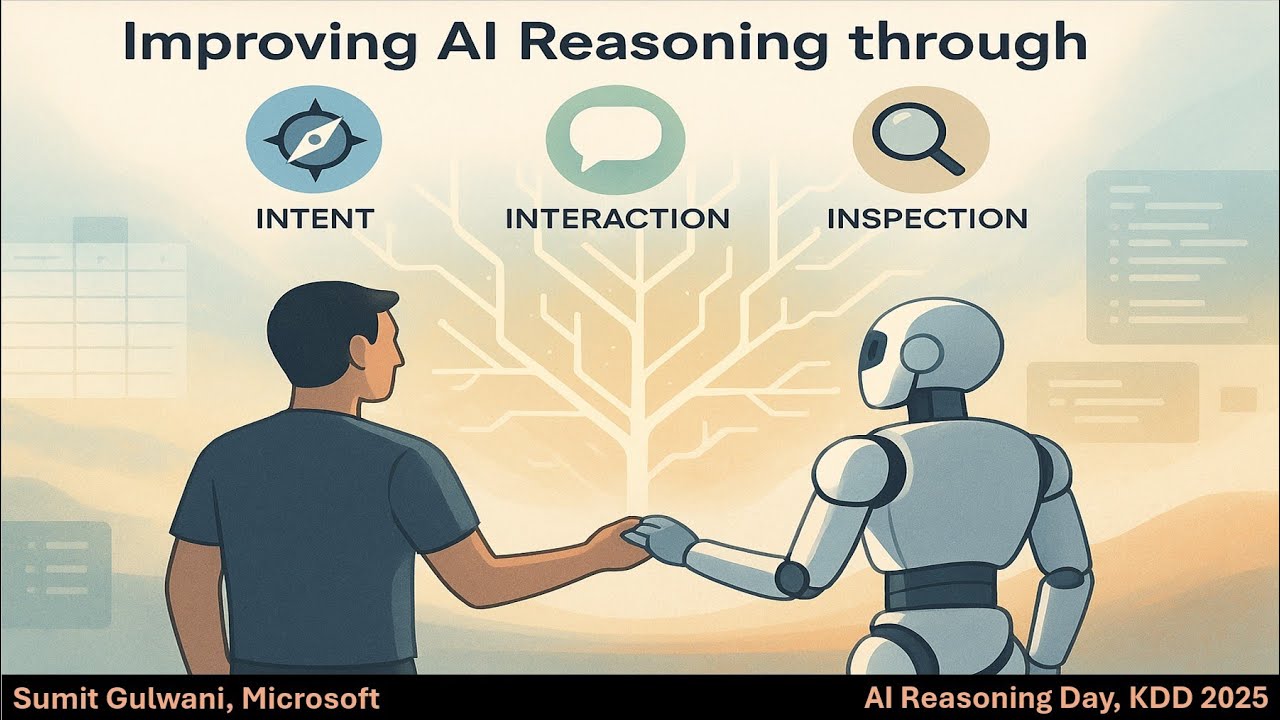
Jennifer Neville discusses her research into "surprising failures" in AI systems, where models, particularly LLMs, struggle with complexity in realistic user workflows. Her team focuses on practical evaluation for multi-turn conversations and agentic knowledge work, emphasizing the need for robust AI that understands context and user intent over time. She offers insights into bridging the gap between user expectations and AI capabilities, advocating for detailed user feedback and outlining the future of human-AI collaboration.