Ai alignment

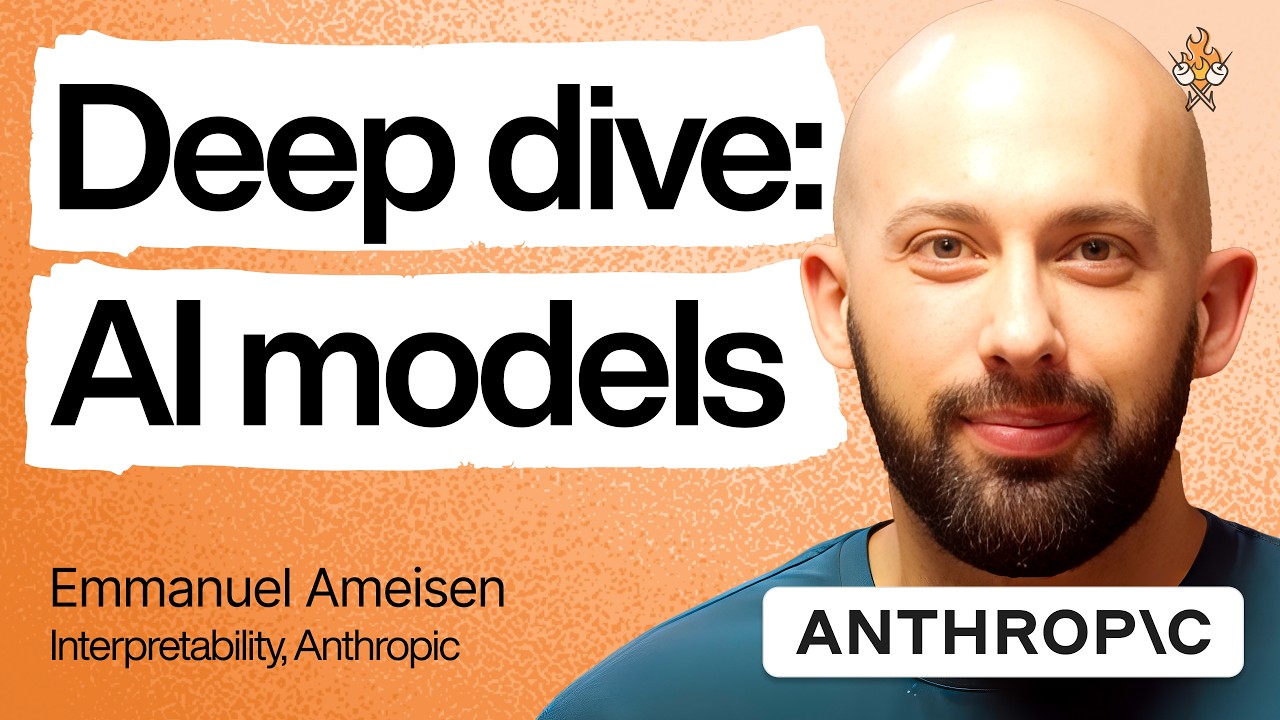
A mind-expanding conversation on how models actually work | Emmanuel Ameisen (Anthropic)

A mind-expanding conversation on how models actually work | Emmanuel Ameisen (Anthropic)

Emmanuel Ameisen, an interpretability researcher at Anthropic, explains how the team looks inside models like Claude to understand how they actually think. The conversation covers why next-token prediction hides real planning and conceptual representation, why models are grown rather than built, how intermediate activations reveal structure, why anthropomorphic framing can be useful, how smooth scaling produces sudden capability thresholds, and how interpretability ties into alignment, safety, and the broader question of what these systems are.
David Silver and Lasse Espeholt of Ineffable Intelligence: A Superlearner for the Age of Experience

David Silver and Lasse Espeholt of Ineffable Intelligence: A Superlearner for the Age of Experience

David Silver, co-founder of Ineffable Intelligence, outlines his bold vision for building a "superlearner"—an AI that discovers science, mathematics, and language autonomously, free from human data or explicit guidance. Drawing parallels to AlphaGo Zero's success, Silver argues that human-language reasoning is a ceiling, not a foundation, for advanced AI. He details their approach using complex simulated "crucibles" and simple rewards, aiming to develop the "science of superintelligence" in simulation for safety and accelerated progress. With a powerful GPU cluster and a small, elite team, Silver forecasts strong evidence within a year and superintelligence within three.

Better AI Starts With Better Verification

Better AI Starts With Better Verification

Halluminate, a Y Combinator S25 company, builds RL environments and benchmarks that teach AI models to do non-coding knowledge work, starting with financial services. In this fireside with YC Partner Jon Xu, co-founders Jerry Wu and Wyatt Marshall trace their pivot from evals to training environments, explain why verification quality matters more than task volume, and outline a roadmap toward multi-agent simulated companies. They also address reward hacking, alignment as an industry-wide responsibility, and what they look for in new hires.

Are AI labs ignoring cybersecurity experts?

Are AI labs ignoring cybersecurity experts?

This podcast explores the friction between frontier AI labs and cybersecurity experts, who disagree on AI safety priorities (alignment vs. traditional controls). It discusses the dual risks of open-weight AI models enabling sophisticated hacks like the TikTok camera exploit, and the challenges of CISA's call for transparent breach disclosures amidst corporate self-interest and the complexities of global AI regulation.

Building the Safety Layer for AI Agents

Building the Safety Layer for AI Agents

Raindrop is building the safety layer for AI agents, detecting and preventing production failures like hallucinations and failed tool calls. The company addresses the paradox that as agents become more capable, they introduce greater complexity and more ways for things to go wrong. Their new Raindrop Simulations product catches critical failures in CI before they ever reach production, democratizing a capability previously limited to large AI labs.

OpenAI researcher on agent swarms & recursive self-improvement

OpenAI researcher on agent swarms & recursive self-improvement

Noam Brown discusses OpenAI's multi-agent system, which solved a Millennium Prize Problem using 10,000 agents. He explores the implications of this massive parallelization for AI capabilities, the rapid progress in mathematics, and the accelerating pace of AI development. A significant portion of the conversation is dedicated to the critical challenges of AI alignment, particularly in light of incidents like the 'Hugging Face' event, and how to ensure models remain aligned during Recursive Self-Improvement (RSI) as their capabilities and operational horizons expand rapidly.